Two tokensbefore it'swritten.

RAG hallucination detection read out of a transformer's hidden states, while the answer is still forming.

Answer under testDrift
Qwen2.5-1.5B, frozen composite 
0.6511
Composite AUROC on the RAGTruth test split
+0.0405
Over the attention-entropy baseline of 0.6106
t−2
Where drift peaks, before onset, p = 2.86e-5
0.6450
HaluEval zero-shot, with nothing refit

Read it the way the model does.

The retrieved context says Paris, 1889, the Exposition Universelle. The model wrote something else. Scroll, and the answer colours in at the pace the detector sees it: cold where the representation stays on the faithful manifold, hot where it leaves.

Retrieved context
The Eiffel Tower is located in Paris, France. It was designed by Gustave Eiffel's engineering company and was completed in 1889 for the Exposition Universelle.
Tokens read
0 / 22
Peak drift so far
0.00waiting
Flagged span
none yettop-5 consensus across Mahalanobis, logit lens and PCA residual

Five readings off one forward pass.

The prompt runs twice, once with the retrieved evidence and once with an empty context. Four signals fuse into the frozen composite. The fifth intervenes on the network directly, to check the other four are measuring something causal.

Pipeline Architecture & Causal Flow Click any block to inspect reading
1 · Paired Forward Passes q + Evidence D  vs  q + Empty Context ∅ 2 · Hidden-State Residual Hooks h_t^(ℓ) across last 18 layers of Qwen2.5-1.5B Cosine Drift δ AUROC 0.5989 · w 0.383 Trajectory instability Mahalanobis m AUROC 0.5389 · w 0.164 Off-manifold shift Logit Lens Λ AUROC 0.5732 · w 0.206 Depth disagreement PCA Residual ρ AUROC 0.5490 · w 0.247 Subspace escape Causal Patching Localisation Only Bidirectional CIE 4 · Robust Z-Score Fusion (Frozen) z_i = (x_i − med) / IQR  ·  s = Σ w_i · z_i 5 · Pre-Generation Score · AUROC 0.6511 Peaks at t−2 before onset  ·  ECE 0.0678

Play a real run, token by token.

Every number below came out of Qwen2.5-1.5B against this repository's frozen stats.pt. Press play and the answer decodes at generation pace while the drift trace follows the playhead.

Retrieved context

Answer under test

0 / 0
on manifolddrifting

space play   step   1 to 5 switch case

Where this is honest. At 0.65 AUROC the sample-level score separates the two classes on average and not case by case: the grounded Apollo answer actually outscores the fabricated Eiffel one. The token ranking is the part that carries weight, and it is pulled hard toward numeric spans. On the Eiffel run those spans are the invented ones. On grounded runs, correct dates get flagged too. That is what 0.65 looks like from the inside.


What it scores, and where it loses.

RAGTruth held-out test: 2,655 responses, 38.9% hallucination rate, 1,000-iteration bootstrap intervals. Switch the column. The composite does not win on every axis, and calibration tells a different story from ranking.

The case for 0.65. One forward pass of a 1.5B model, no sampling, no external judge. It closes 19.51% of the distance from the attention-entropy baseline to ReDeEP at 0.82, and 16.44% of the distance to LUMINA at 0.87, while cutting expected calibration error from 0.2230 to 0.0678.


The finding the whole thing rests on.

Align every hallucinated span at its first hallucinated token, then look backwards.

t−2

Cosine drift peaks two positions before the model writes the first hallucinated token. Mann-Whitney U, p = 2.86 × 10⁻⁵.

The representation has already left the faithful manifold while the text still reads clean. Without that gap there is no pre-generation detection, only faster post-hoc detection.


Two ways of not fooling ourselves.

Correlation is cheap. One half of this section intervenes on the network directly; the other moves the whole detector onto a dataset it was never fitted on.

Bidirectional activation patching

50+ paired examples. Activations are swapped between a faithful run and a hallucinated one in both directions, and the change in target-token probability is measured. Every group clears p < 0.05, and early attention dominates by an order of magnitude.

Zero-shot transfer to HaluEval

Same weights, same training medians and IQRs, nothing re-estimated, moved straight onto HaluEval-QA. The fused score barely moves. Individual signals swing hard in both directions, which is the whole argument for fusing them.


Everything the pipeline plots.

Written straight out of the analysis scripts in the repository. Click any figure to open the interactive high-resolution viewer.
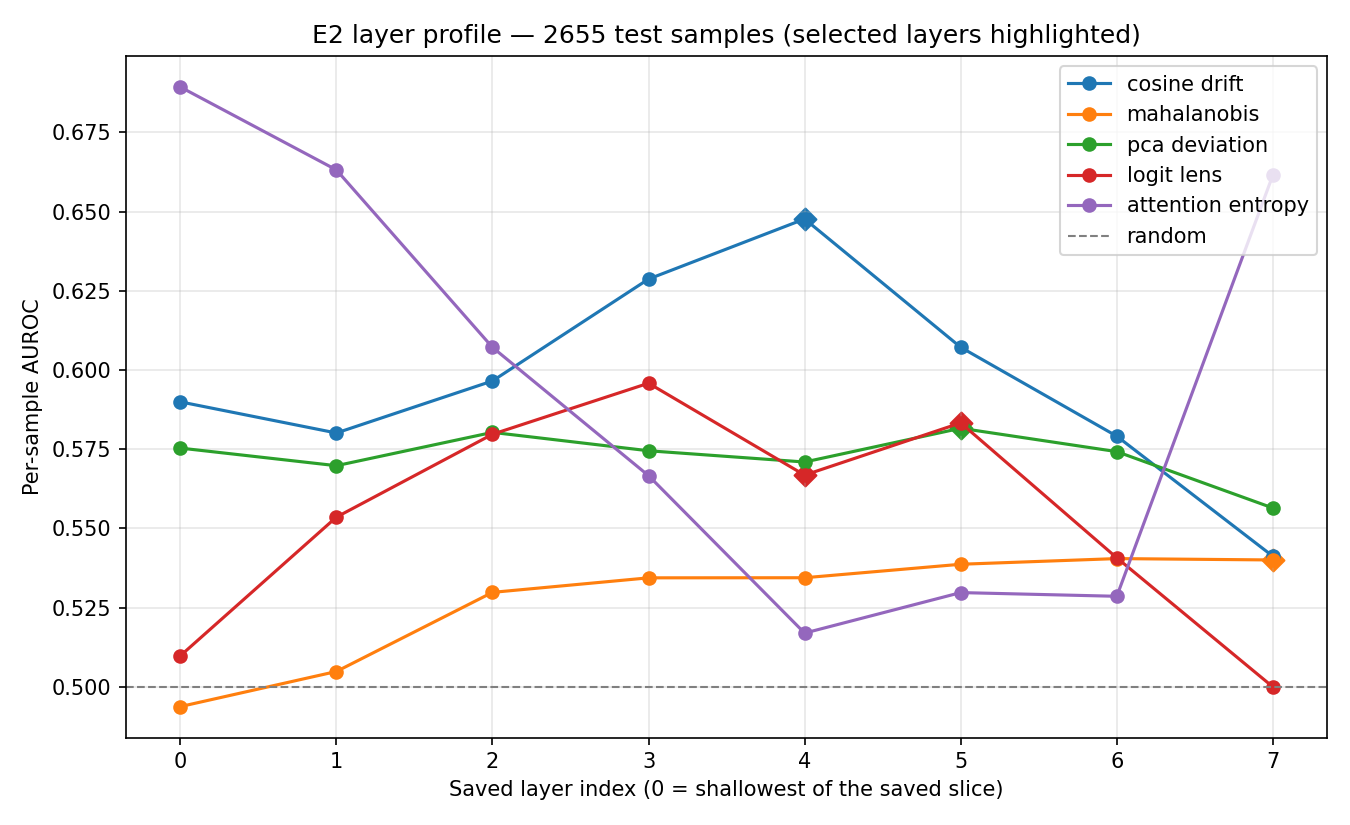
E2 Layer profile
Core finding
Per-layer point-biserial correlation profile Click to inspect

Layer localisation profile

Discriminative signal concentrates in middle-to-late Qwen layers (saved indices 5–15 correspond to model layers 15–25). The top three predictive layers are 21, 23, and 22.

python NLP-sub/pipeline/plot.py
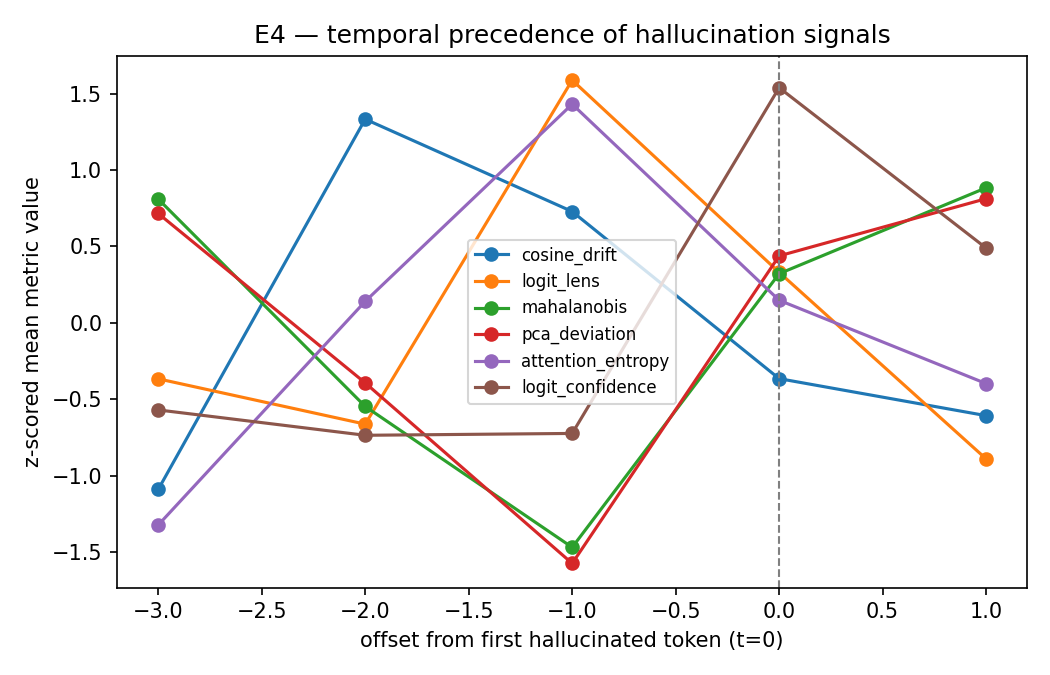
E4 Pre-onset peak
Key discovery
Drift signals aligned to hallucination onset Click to inspect

Pre-onset temporal precedence

Aligned to first hallucinated token (t = 0). Cosine drift peaks at t−2 before the model commits the error to text (Mann-Whitney U, p = 2.86 × 10⁻⁵).

python NLP-sub/scripts/e4_temporal.py
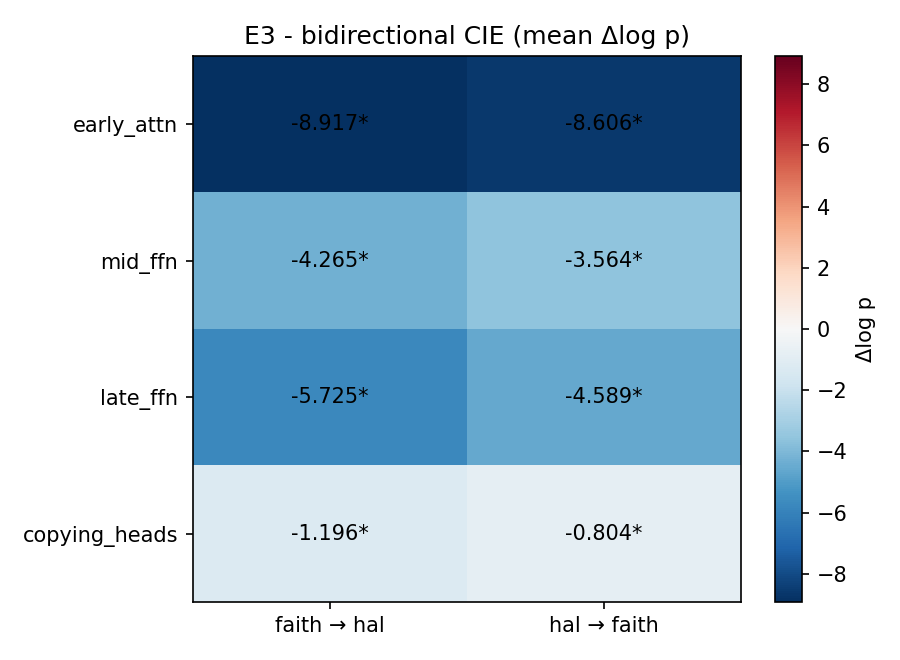
E3 Causal patching
Causal CIE
Bidirectional causal indirect effect by component group Click to inspect

Bidirectional activation patching

50+ paired counterfactuals. Early attention dominates causal influence by an order of magnitude (CIE −1.0991, p < 0.05 across all component groups).

python NLP-sub/scripts/e3_patching.py
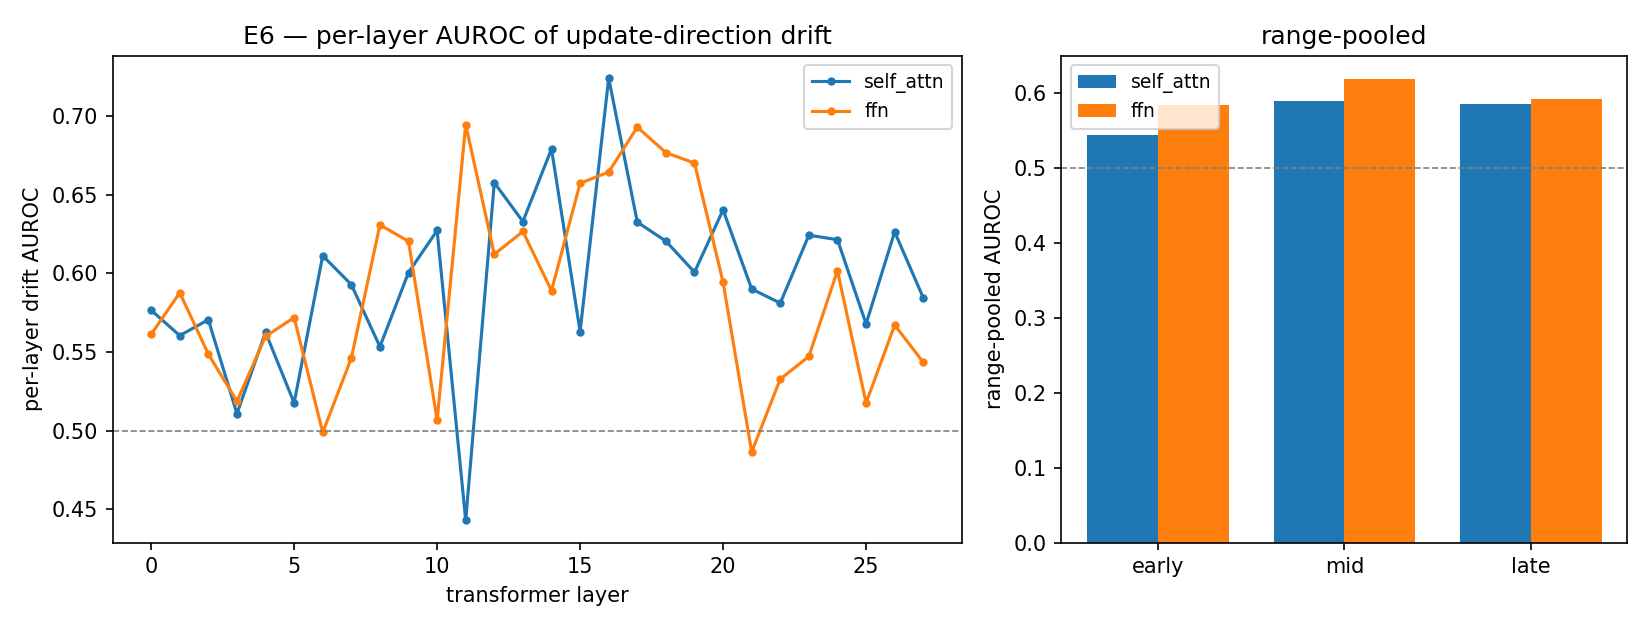
E6 Component drift
Mechanistic
Self-attention versus feed-forward drift contribution Click to inspect

Self-attention vs FFN component drift

Decomposing residual-stream updates shows FFN key-value memories driving mid-to-late layer representation drift during factual hallucinations.

python NLP-sub/scripts/e6_component_drift.py
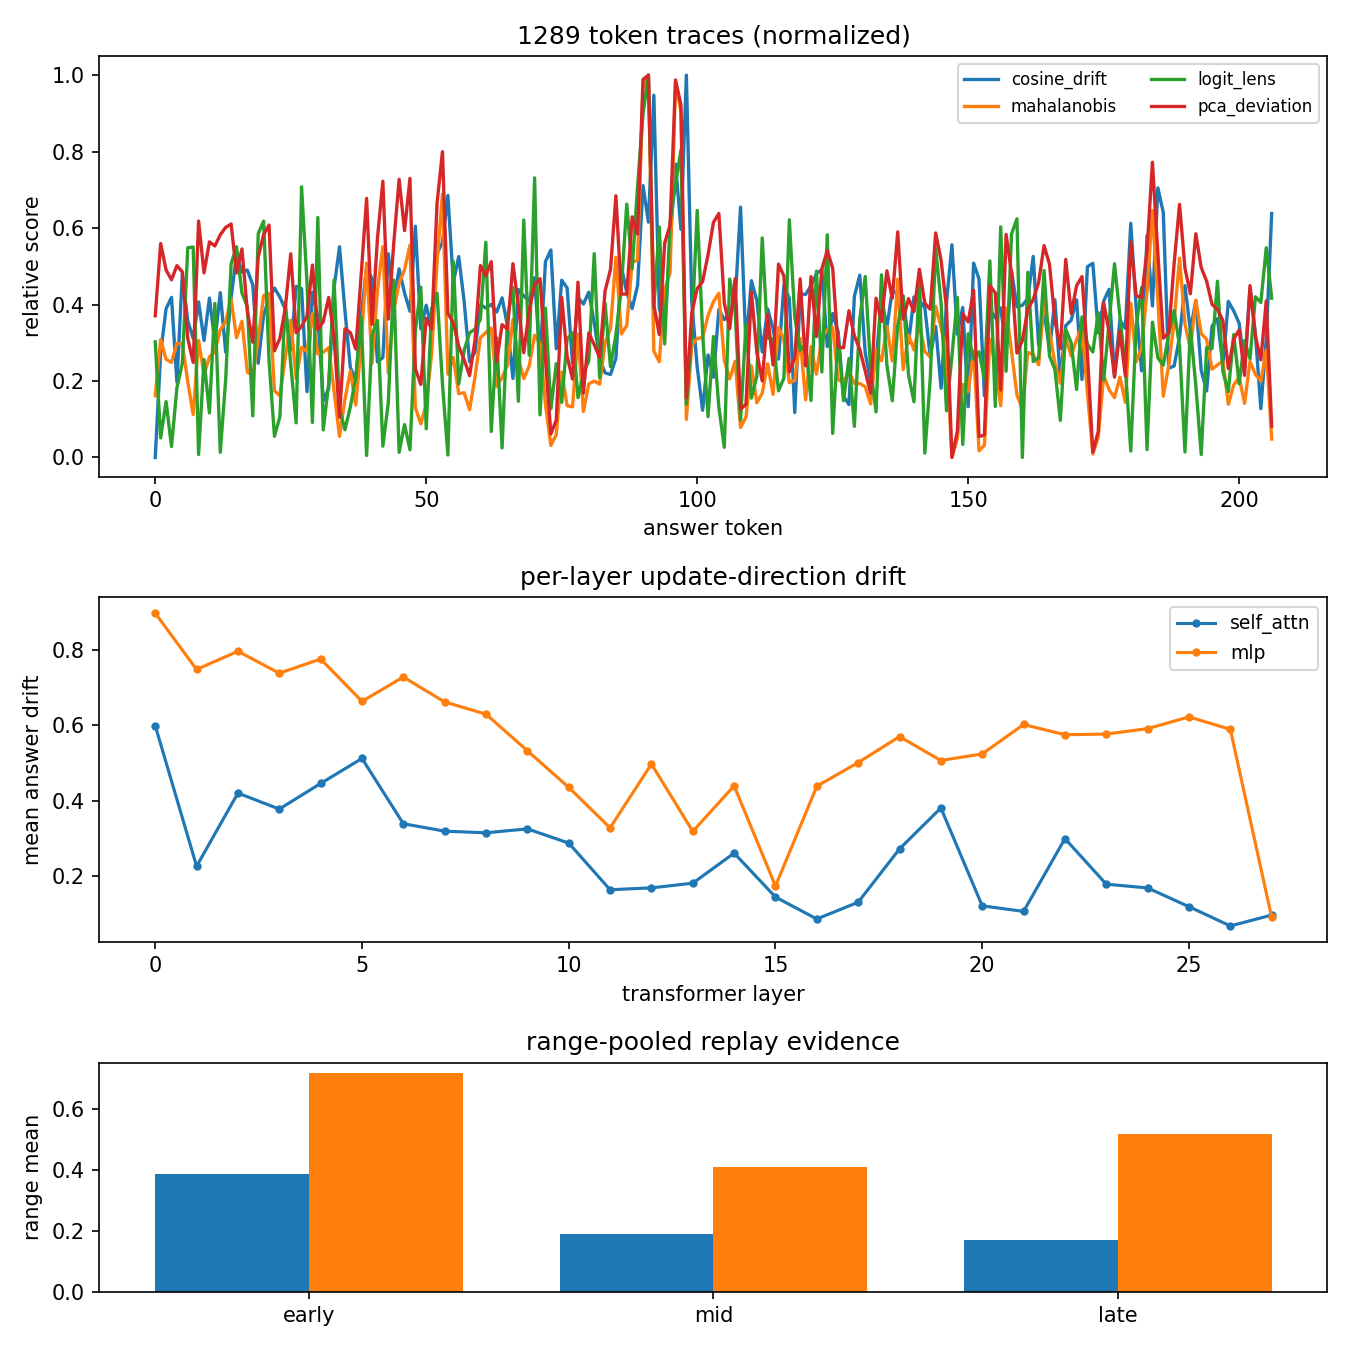
E7 Sample #1289
False negative
False negative trace, sample 1289 Click to inspect

Missed hallucination trace

A fabrication the composite missed. Internal drift remained low because the invented entities closely mirrored the vocabulary and syntax of training examples.

python NLP-sub/scripts/e7_failures.py
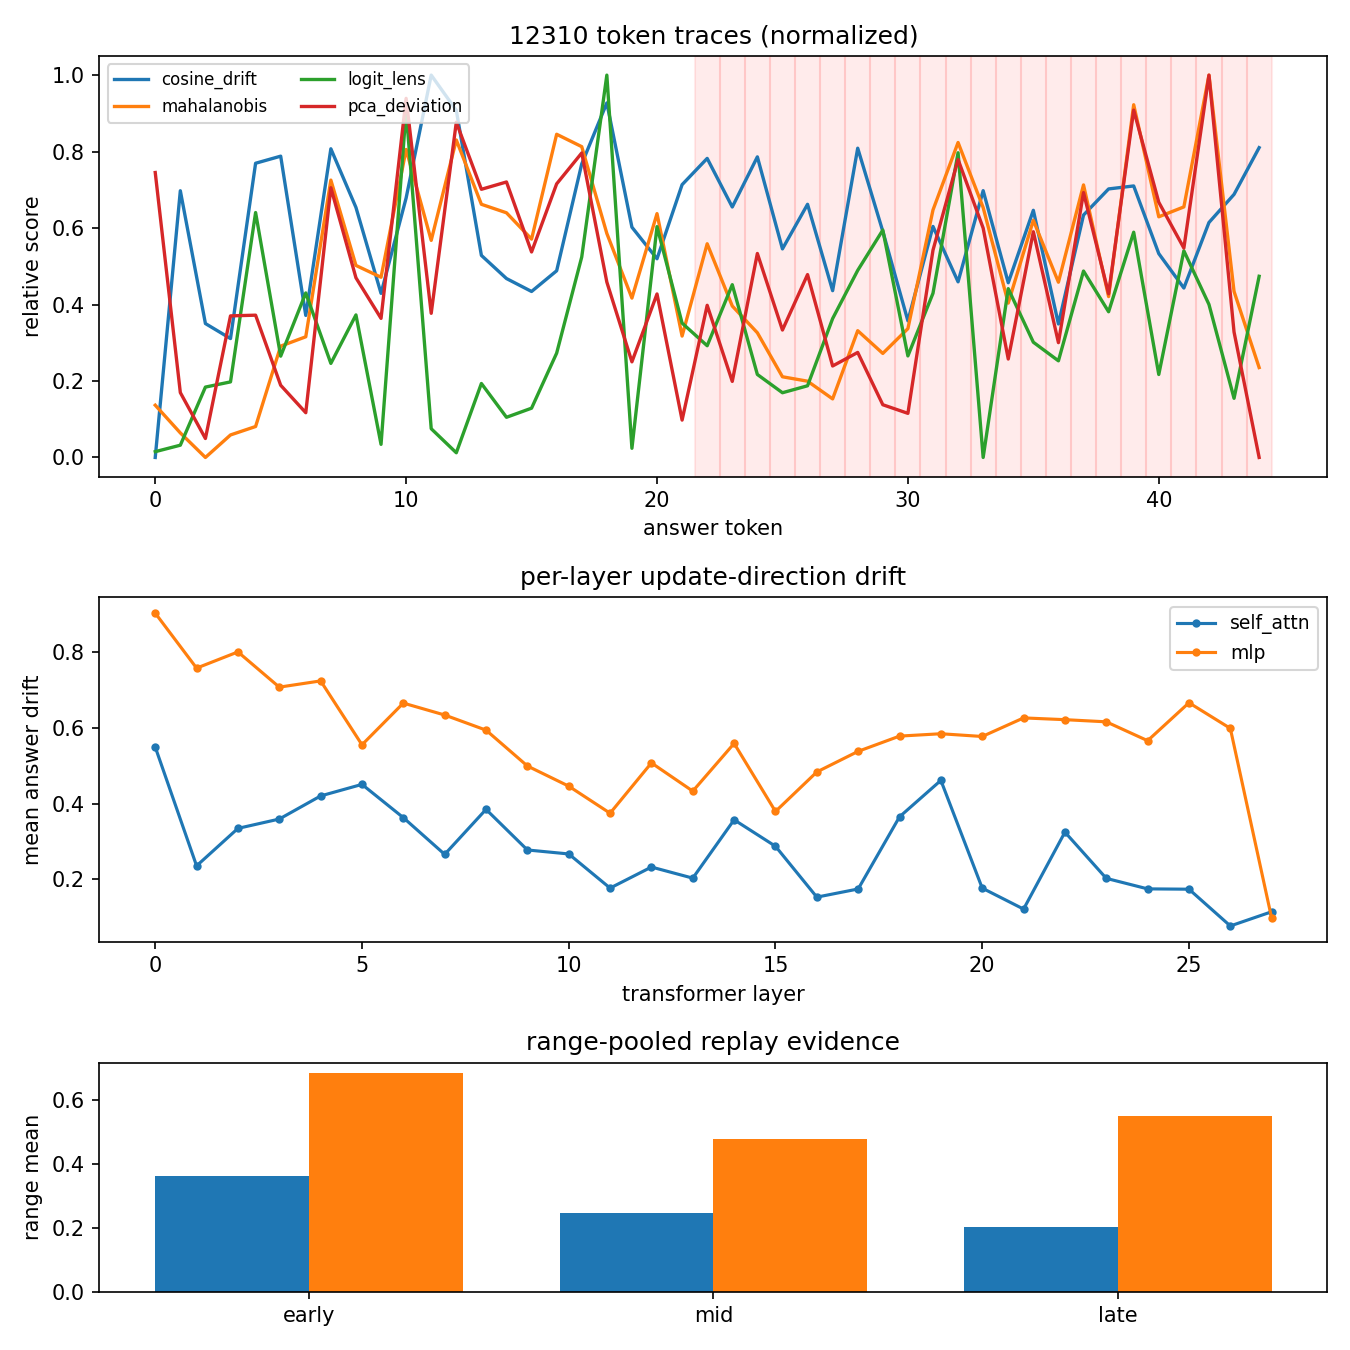
E7 Sample #12310
False positive
False positive trace, sample 12310 Click to inspect

Faithful continuation that drifted

A grounded answer that drifted anyway. Numerical dates triggered off-manifold Mahalanobis warnings despite being factually grounded in the prompt context.

python NLP-sub/scripts/e7_failures.py
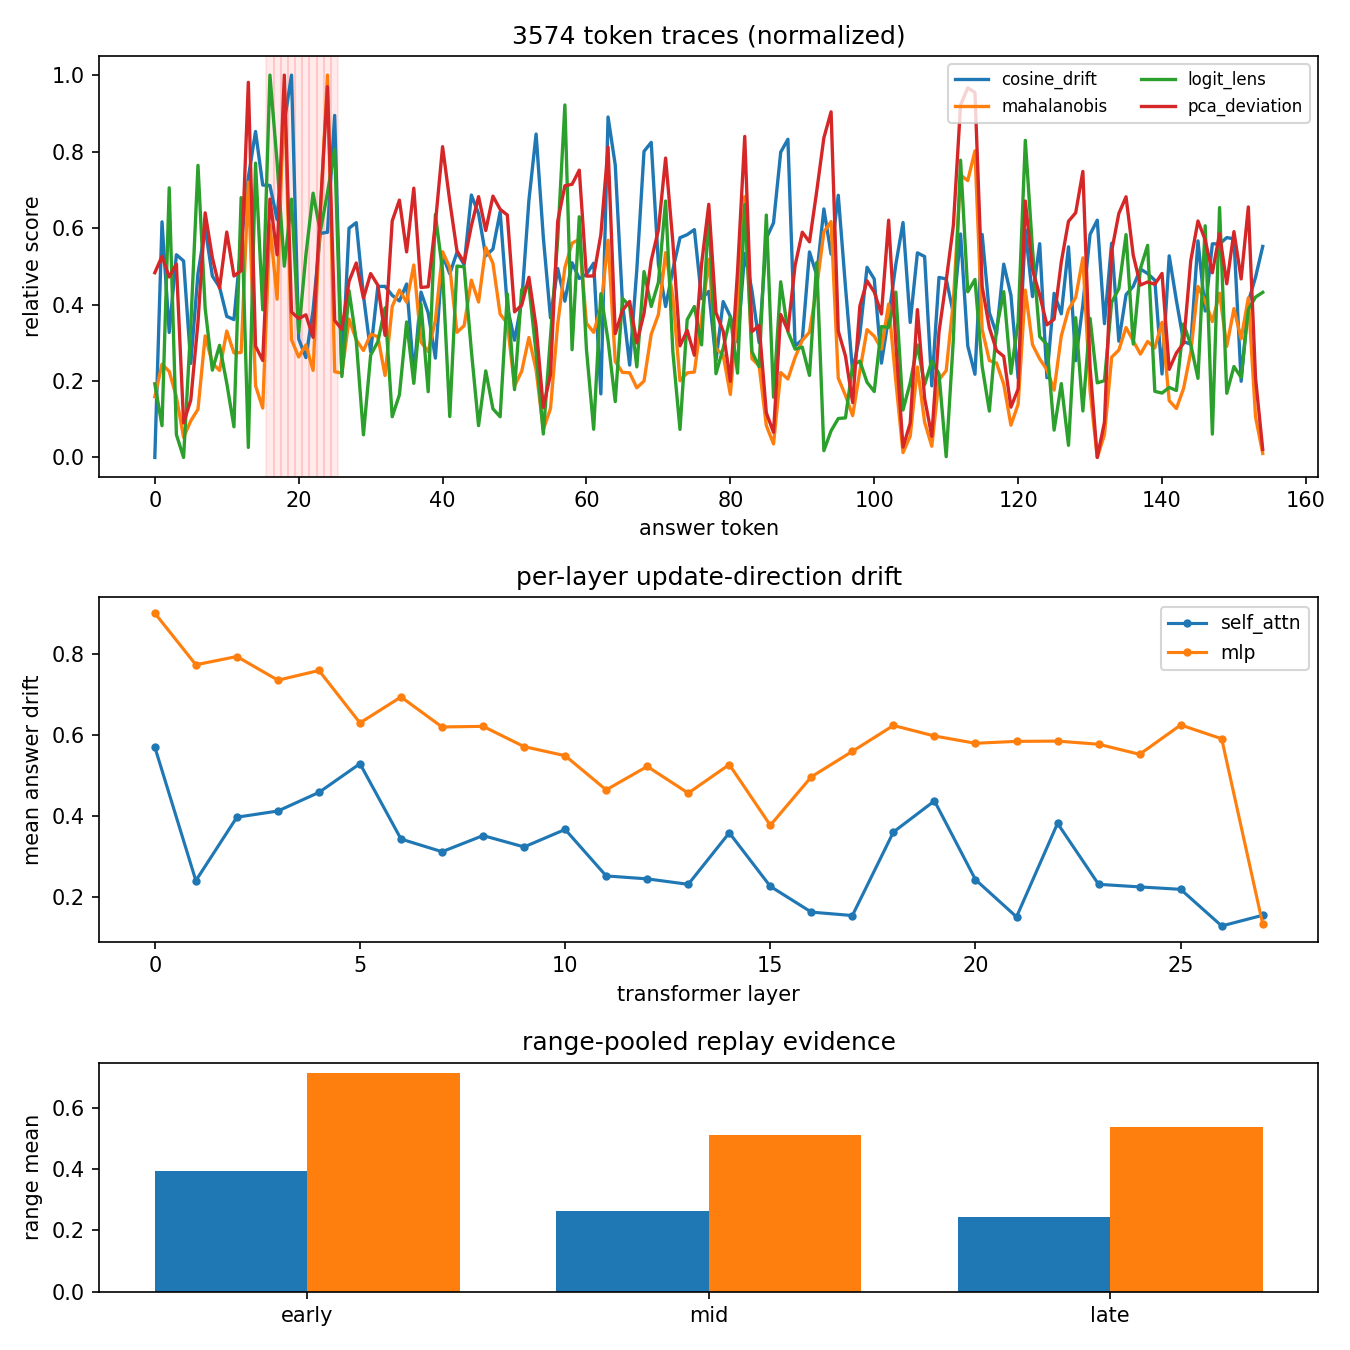
E7 Sample #3574
Contradiction
Metric disagreement trace, sample 3574 Click to inspect

Signal contradiction trace

Where the five signals contradict each other. Mahalanobis and PCA indicate substantial departure while logit lens remains confident in the evidence context.

python NLP-sub/scripts/e7_failures.py

Every number here is regenerable.

Statistics are fit on train only, frozen, then applied to test. Nothing on this page touches a test-set statistic.

01

Environment and data

git clone https://github.com/Chirudeva-Reddy/NLP-Proj.git && cd NLP-Proj
python3 -m venv .venv && source .venv/bin/activate
pip install -r Requirements.txt

# RAGTruth goes in dataset/ragtruth/
#   response.jsonl      answers plus character-level hallucination spans
#   source_info.jsonl   source documents and retrieval context
02

Infer, fit, score, evaluate

python NLP-sub/pipeline/1-infer.py --model Qwen/Qwen2.5-1.5B --layers last18 --device auto \
  --output-dir NLP-sub/outputs/artifacts

python NLP-sub/pipeline/2-fit.py --artifacts-dir NLP-sub/outputs/artifacts \
  --output NLP-sub/outputs/stats.pt --pca-components 16

python NLP-sub/pipeline/3-score.py --artifacts-dir NLP-sub/outputs/artifacts \
  --stats NLP-sub/outputs/stats.pt --output-dir NLP-sub/outputs/scores_test --split test

python NLP-sub/pipeline/4-eval.py --scores-dir NLP-sub/outputs/scores_test \
  --aggregate max --n-boot 1000
03

Score your own context and answer

python NLP-sub/scripts/live_demo.py --profile local --show-aggregates \
  --input-file NLP-sub/examples/live_demo_inputs/eiffel_tower_hallucinated_passage.json

# drop "passage" from the JSON and the model writes the answer, then scores itself
04

Rebuild the data behind this page

cd NLP-sub
python scripts/export_demo_json.py --stats outputs/stats.pt --output ../docs/site/demo_runs.json

# preview: cd ../docs && python3 -m http.server 8000

Authors.

CS F429 Natural Language Processing, BITS Pilani Dubai Campus, supervised by Prof. Elakkiya Rajasekar. May 2026.

Sanya Wadhawan
2023A7PS0296U
Methodology framing, dataset preprocessing, RAGTruth pipeline integration
Chirudeva Reddy
2023A7PS0331U
Experimental setup, composite metric fusion, causal patching analysis
Yusra Hakim
2022A7PS0004U
Related work survey, mechanistic interpretability literature review
Joseph Cijo
2022A7PS0019U
Introduction, result tables, baseline evaluation, report documentation

Formal Academic Research Report (14 Pages)

Comprehensive manuscript covering theoretical formulation, 5-signal derivations, bidirectional causal patching, appendices, and signed individual contribution statements.

Read PDF Manuscript
@techreport{wadhawan2026pregen,
  title       = {Pre-Generation Hallucination Detection via Internal Representation Drift},
  author      = {Wadhawan, Sanya and Reddy, Chirudeva and Hakim, Yusra and Cijo, Joseph},
  institution = {BITS Pilani, Dubai Campus},
  year        = {2026}, month = {May},
  url         = {https://github.com/Chirudeva-Reddy/NLP-Proj}
}